arXiv · 2025 · Preprint
Shuster and Nachmani · → Paper · Demo: ✗ · Code: ✓
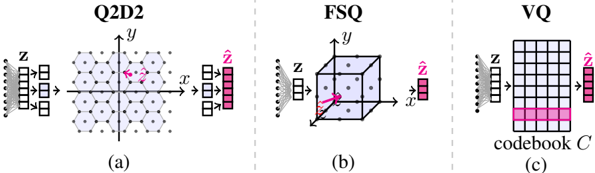
Introduces Two-Dimensional Quantization (Q2D2), a codec quantizer that jointly quantizes pairs of latent channels onto structured 2D grids (hexagonal, rectangular, or rhombic), retaining the codebook-collapse robustness of Finite Scalar Quantization while capturing inter-channel correlations that FSQ’s per-channel scalar quantization ignores.
Problem
Neural audio codecs built on Residual Vector Quantization (RVQ) or Vector Quantization (VQ) achieve strong reconstruction quality but are difficult to optimize: as codebook size grows, many codewords go unused (the well-documented codebook-collapse problem), and mitigations such as codebook reinitialization or stochastic reformulations add engineering complexity. Finite Scalar Quantization (FSQ) sidesteps collapse entirely by quantizing each latent channel independently onto a fixed scalar grid, guaranteeing high utilization by construction, but this strict channel independence means FSQ cannot capture correlations between feature dimensions, limiting representational capacity. The paper asks whether a quantizer can retain FSQ’s simplicity and utilization guarantees while still modeling cross-channel structure, without reintroducing the instability of high-dimensional VQ.
Method
Q2D2 is built directly on the WavTokenizer framework: the encoder and decoder are unchanged from WavTokenizer, and only the quantization layer is replaced (§Appendix A). The encoder’s final-layer output is projected via a learned affine map to a d-dimensional space (d must be even), followed by a tanh nonlinearity that bounds each channel to [-1, 1]. Each channel is then rescaled by a per-dimension factor tied to its chosen number of quantization levels l_i, and the d channels are reshaped into d/2 feature pairs. Each pair is snapped to the nearest point in a fixed two-dimensional grid drawn from one of three tiling schemes: hexagonal (Algorithm 1), rectangular (Algorithm 2), or rhombic (Algorithm 3), each parameterized by the number of levels and a spread factor per axis (§3.1). The overall implicit codebook is the product of all per-pair grids, so its size scales identically to FSQ and VQ codebooks without requiring a learned embedding table. Gradients are propagated through the discrete quantization step with a Straight-Through Estimator (STE), the same mechanism used by VQ and FSQ. Because the grids are fixed and analytic, Q2D2 introduces no additional learned parameters beyond lightweight linear projection layers scaling with d, unlike VQ, whose codebook parameter count scales with |C| · d (§3.3).
The main reconstruction models were trained on approximately 8K hours spanning speech (LibriTTS, VCTK, a 3,000-hour CommonVoice subset), general audio (a 2,000-hour AudioSet subset), and music (Jamendo, MUSDB18), following the WavTokenizer data recipe (§4.1). A separate set of models used for baseline comparisons was trained on roughly 150K hours of multilingual speech drawn from Emilia (six languages) and MLS (eight languages). Ablation-study models were trained on the 585-hour English LibriTTS corpus alone. Models were trained with AdamW at an initial learning rate of 8e-5 with cosine decay, batch size 16, for approximately 40 epochs, on 24 kHz audio. The paper reports model size only in illustrative terms relative to VQ (not as an absolute parameter count for Q2D2 itself). Downstream generative usability was tested by training an autoregressive TTS model, an adaptation of the ParlerTTS framework (600M parameters) following the MusicGen paradigm, on top of Q2D2 tokens, DAC tokens, and WavTokenizer tokens for comparison (§4.2).
Key Results
On LibriSpeech test-clean (Table 2), Q2D2 at 333 tokens/second (6.9 kbps, single quantizer) reaches UTMOS 4.07, matching or exceeding DAC (900 tokens/s across 9 quantizers, UTMOS 4.00) and Encodec (600 tokens/s across 8 quantizers, UTMOS 3.09). At 75 tokens/second and 1 kbps, Q2D2 outperforms DAC (100 tokens/s) across all reported metrics and outperforms the WavTokenizer baseline (75 tokens/s) on PESQ, STOI, and V/UV F1 on LibriTTS test-clean and test-other (§4.2, Table 2). In a controlled, same-framework comparison isolating only the quantizer (Table 3), Q2D2 at 1 kbps consistently outperforms both FSQ and VQ (as used in WavTokenizer) on UTMOS, PESQ, STOI, and V/UV F1 across LibriTTS test-clean, LibriTTS test-other, and LJSpeech, with all three quantizers trained identically apart from the quantization layer.
Subjectively, Q2D2 at 3.3 kbps scores 98.05 MUSHRA, exceeding DAC at 9 kbps (92.64) and Encodec at 6.0 kbps (94.41); Q2D2 at 1 kbps (94.68) is comparable to WavTokenizer at 0.9 kbps (94.83) (§4.2, Table 5). On the downstream autoregressive TTS task using the ParlerTTS 600M setup (Table 6), Q2D2 tokens at 1 kbps yield better CMOS-Q and CMOS-P than WavTokenizer tokens at 0.9 kbps, and approach DAC’s scores despite using a single quantizer versus DAC’s nine. On the ARCH semantic-representation benchmark (Table 7), Q2D2 with only 53 tokens/second outperforms DAC and Encodec configurations using 100–900 tokens across most of the twelve speech, music, and audio datasets. Ablations (§5) show the rhombic grid consistently outperforms rectangular and hexagonal tilings, attributed to its higher packing efficiency, and that a 6-dimensional, 3-pair configuration outperforms both higher- and lower-dimensional alternatives at matched bitrate. Codebook utilization stays at 92–99% across the tested grid-level configurations (Table 10), in contrast to the well-documented under-utilization problem in VQ/RVQ codebooks as size increases.
Novelty Assessment
The core contribution is architectural: a new quantization layer that groups latent channels into pairs and quantizes each pair jointly against a structured 2D geometric grid (hexagonal, rectangular, or rhombic), rather than quantizing channels independently (FSQ) or via a learned high-dimensional codebook (VQ/RVQ). This is a genuine structural departure in how the quantization step is formulated, not merely a new training recipe or a new application of an existing quantizer. The encoder and decoder themselves are unchanged from WavTokenizer; the paper’s contribution is confined to the quantization layer, and the authors are explicit about this in the appendix. The experimental contribution is broad: the same quantizer is validated across speech, general audio, and music domains, against a wide set of SOTA codec baselines, with both objective and subjective (human-rated MUSHRA and CMOS) evaluation, plus a downstream autoregressive-TTS usability check and an ARCH semantic-representation benchmark. The geometric framing (packing efficiency arguments for why rhombic tiling outperforms hexagonal and rectangular tiling) is a genuinely new way of reasoning about the quantization-error trade-off in audio codecs, distinct from prior codebook-collapse mitigations.
Scope caveat for this wiki: Q2D2 is presented as a general-purpose audio-coding quantizer, not a speech-specific method. Its training and evaluation explicitly span speech, general audio, and music domains, and roughly half of its main-results tables (LibriSpeech, LibriTTS, LJSpeech) are speech-specific while the ARCH benchmark and part of the training data cover music and environmental audio. It is included here on the same basis as other general-purpose neural codecs already in this corpus (e.g., EnCodec, WavTokenizer): a substantial share of its training data, evaluation benchmarks, and one dedicated downstream experiment (autoregressive TTS token quality) are speech-specific, and it is presented as a drop-in quantizer replacement for the same codec stacks used by speech-generation systems.
Field Significance
High
High — Q2D2 introduces a structurally new quantization primitive for neural audio codecs that plausibly generalizes beyond this paper’s own experiments, since it is a drop-in replacement for the quantization layer in any encoder-decoder codec architecture. It provides a new design axis (grid geometry) for the codebook-utilization/reconstruction-quality trade-off that prior VQ- and FSQ-family methods did not offer, and demonstrates competitive-to-superior reconstruction at markedly lower token rates than several widely used baselines.
Because the method modifies only the quantization layer of an existing framework (WavTokenizer) and reuses its encoder, decoder, and training recipe, the paper’s contribution is narrower than a full codec redesign; its significance rests specifically on the quantization mechanism and the empirical evidence that geometric 2D tiling can outperform both FSQ and VQ under matched conditions.
Claims
- supports: Jointly quantizing pairs of latent channels onto a structured 2D geometric grid can capture inter-channel correlations that per-channel scalar quantization (FSQ) discards, while preserving FSQ’s high codebook utilization without a learned codebook.
Evidence: In a controlled comparison that changes only the quantization layer within an otherwise identical codec framework, Q2D2 at 1 kbps outperforms both FSQ and VQ on UTMOS, PESQ, STOI, and V/UV F1 across LibriTTS test-clean, LibriTTS test-other, and LJSpeech. (§4.2, Table 3)
- supports: The choice of 2D tiling geometry materially affects reconstruction quality at matched bitrate and level count, with denser, more isotropic packings yielding lower quantization error.
Evidence: Under matched conditions, rhombic grids consistently outperform rectangular and hexagonal grids on PESQ and STOI; the authors attribute this to the rhombic lattice’s higher packing efficiency (smaller, more uniformly distributed neighbor distances) compared to the other two tilings. (§5, Table 8)
- supports: A single-quantizer, geometry-aware codec can match or exceed the codebook utilization of FSQ-family quantizers while operating at substantially lower token rates than multi-quantizer RVQ codecs, without auxiliary stabilization tricks such as commitment losses or codebook reseeding.
Evidence: Across tested grid-level configurations, codebook utilization ranges from 92.18% to 99.47%, achieved without commitment losses, EMA, or codebook reinitialization, the auxiliary techniques VQ and RVQ require to avoid collapse. (§5, Table 10)
- complicates: Discrete codec tokens optimized primarily for reconstruction fidelity are not automatically validated as suitable inputs for downstream autoregressive generation; that transfer must be checked separately.
Evidence: The paper trains a separate 600M-parameter ParlerTTS-based autoregressive TTS model on Q2D2, WavTokenizer, and DAC tokens specifically to verify generative usability, reporting CMOS-Q and CMOS-P rather than assuming reconstruction-quality rankings transfer directly to generation quality. (§4.2, Table 6)
- complicates: A quantizer’s core design choices interact with each other in ways that are not decomposable; changing dimensionality or level count while holding grid geometry fixed shifts the optimal operating point rather than uniformly improving or degrading quality.
Evidence: The dimension-size ablation shows a 6-dimensional (3-pair) configuration outperforms both an 8-dimensional, lower-resolution configuration and a 4-dimensional, higher-resolution configuration at the same 1 kbps bitrate, indicating a non-monotonic trade-off between dimensionality and per-dimension resolution. (§5, Table 9)
Limitations and Open Questions
The method is validated only within the WavTokenizer encoder-decoder framework; the encoder and decoder architectures themselves are not varied, so it remains untested whether the quantization-layer gains transfer to codecs with substantially different encoder-decoder designs. The paper’s own future-work section notes that extension to 3D (or higher-dimensional) geometric tilings is left unexplored, and that the audio and music domains, though included in training, receive comparatively less dedicated evaluation than speech. The downstream generative usability check uses a single TTS architecture (ParlerTTS-based, 600M parameters) and reports only CMOS-Q/CMOS-P on LibriTTS; broader downstream validation (e.g., zero-shot TTS, other speech-LM backbones, or VC) is not attempted. Model parameter counts for the full Q2D2 system are not reported in absolute terms, only relative to VQ’s codebook parameter cost.
Wiki Connections
- Neural Audio Codec — introduces a new quantization-layer design (structured 2D grids) as a direct alternative to the RVQ, VQ, and FSQ mechanisms this concept already covers.
- Subjective Evaluation — conducts MUSHRA listening tests and CMOS-Q/CMOS-P comparative mean opinion score evaluations with real human raters to validate reconstruction and downstream generation quality.
- Autoregressive Codec TTS — validates the resulting codec tokens as inputs to an autoregressive TTS model (ParlerTTS-based, following the MusicGen paradigm), comparing generation quality against DAC and WavTokenizer tokenizations.
- Evaluation Metrics — benchmarks reconstruction and semantic quality across a wide set of established objective (UTMOS, PESQ, STOI, V/UV F1) and subjective (MUSHRA, CMOS) metrics spanning speech, audio, and music domains.
- WavTokenizer — Q2D2 is built directly on the WavTokenizer encoder-decoder framework, replacing only its quantization layer, and WavTokenizer serves as the primary baseline throughout.
- Finite Scalar Quantization — Q2D2’s core motivation is to retain FSQ’s collapse-free, high-utilization properties while overcoming FSQ’s inability to model inter-channel correlations; directly compared under matched conditions.
- EnCodec — used as a multi-quantizer RVQ baseline for reconstruction quality and token-rate comparisons across all main results tables.
- SpeechTokenizer — used as a baseline codec for objective reconstruction comparisons on LibriTTS and LibriSpeech.
- BigCodec — used as a low-bitrate single-quantizer baseline on the LibriSpeech objective reconstruction comparison.
- Vocos — used as a baseline codec (Encodec decoder replacement) for objective reconstruction comparisons.
- Scaling Transformers for Low-Bitrate Speech Coding — used as a baseline in the LibriSpeech low-token-rate reconstruction comparison.
- Mimi — Mimi’s codec is used as a baseline across several token-rate operating points in the LibriSpeech reconstruction comparison.