arXiv · 2026 · Preprint
Heinrich Dinkel et al. (Xiaomi Inc.) · → Paper · Demo: ? · Code: ✓
Introduces DashengTokenizer, a continuous audio tokenizer that injects a low-dimensional acoustic residual into a frozen high-dimensional semantic encoder, and evaluates it as a general-purpose (speech, music, environmental-sound) understanding-and-generation representation, including a direct speech-reconstruction comparison against established speech codecs on SEED-TTS.
Problem
Note on scope: this paper’s own framing is a tri-domain general-purpose audio tokenizer for speech, music, and environmental sound (§1), and every one of its generative demonstrations, text-to-audio (AudioCaps), text-to-music (MusicCaps), and speech enhancement (Valentini/DNS1), is a non-speech-synthesis task; the paper never performs TTS or voice conversion generation. It is included in this wiki narrowly because §5.1 reports a genuine speech-codec reconstruction benchmark on the SEED-TTS (ZH/EN) dataset, evaluated directly against in-corpus speech codecs (Mimi, XCodec 2.0, SNAC, XY-Tokenizer). This page reports only that speech-relevant reconstruction and speech-understanding evidence as Claims; the TTA/TTM/general-audio results are mentioned here for completeness only and are out of this wiki’s scope.
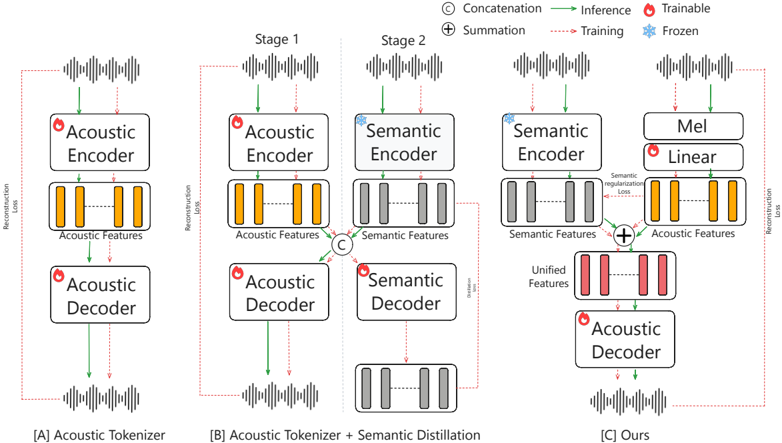
Joint audio understanding and generation typically requires two separate representations: unidirectional semantic encoders that produce coarse, high-dimensional embeddings well suited to discriminative tasks, and low-dimensional acoustic tokenizers (discrete or continuous autoencoders) optimized for high-fidelity waveform reconstruction. Prior attempts to unify the two either (I) run a semantic encoder alongside an independent acoustic tokenizer, which is computationally redundant, or (II) train a single model on both objectives, which tends to sacrifice semantic quality for reconstruction fidelity, or (III) distill semantic knowledge into a low-dimensional acoustic codec through a multi-stage pipeline (the approach taken by the most closely related prior system, Ming-UniAudio / MingTok-Audio, which is speech-only and requires acoustic modeling, semantic distillation, and fine-tuning stages) (§2).
Method
DashengTokenizer inverts the usual distillation direction: rather than compressing semantic information into a low-dimensional acoustic latent, it injects a low-dimensional acoustic residual into a frozen, high-dimensional semantic embedding. Given an input signal, semantic features are extracted from a frozen pretrained encoder (a 630M-parameter, 32-layer Transformer from MiDashengLM, operating at 25 Hz, chosen over alternatives such as Whisper for full training-data reproducibility). In parallel, a lightweight acoustic encoder (0.66M parameters: a 2D convolution over a 128-bin mel-spectrogram with non-overlapping patches, followed by layer normalization) produces an acoustic embedding at the same 25 Hz frame rate. The two are combined by simple additive fusion, z = z_sem + z_ac (§3).
A generator (vocoder) is trained to reconstruct the waveform from this unified feature using a GAN framework with a multi-frequency discriminator, hinge adversarial loss, feature-matching loss, and mel-spectrogram L1 loss. Because unconstrained additive fusion risks letting the acoustic signal overwhelm the semantic one, a semantic-preservation loss L_sem = ||z_sem - z_ac||² regularizes the acoustic branch to stay close to the semantic branch during training (§3). The decoder itself is a scaled Vocos architecture (173M parameters, 12 layers, 1280-dim hidden state) that upsamples the unified 25 Hz feature to a 50 Hz representation before waveform synthesis (Table 2). Only the acoustic encoder, semantic-preservation regularization, and decoder are trained; the semantic encoder is frozen throughout, and it is retained (not discarded) at inference time, avoiding the train/test mismatch that affects semantic-distillation pipelines which drop their semantic decoder after training.
Training uses ~282k hours of audio spanning speech (71%: 21% English, 40% Chinese, 10% other languages, drawn from Emilia, Yodas, LibriLight, CommonVoice15, and AISHELL-1/2/3), music (21%: Million Song Dataset, MTG-Jamendo), and general sound (26%: AudioSet, FSD50K, AudioCaps, CochlScene, ACAVCaps), all resampled to 16 kHz (§4.1). The model trains for one million steps with AdamW, batch size 256, and a cosine-decayed learning rate from 5e-4.
Key Results
The speech-relevant reconstruction result is a direct head-to-head comparison against established speech codecs on the ZH and EN subsets of SEED-TTS, measured with PESQ and STOI at 16 kHz. DashengTokenizer (25 Hz frame rate) substantially outperforms the discrete codec baselines: SNAC (PESQ 1.841/1.804 ZH/EN), Mimi (2.05/2.01), XCodec 2.0 (2.19/2.37), and XY-Tokenizer (2.27/2.14), against DashengTokenizer’s 4.163/4.125 PESQ, while operating at a lower frame rate than the other continuous-tokenizer baselines it is closest to (UniFlow-Audio and MingTok-Audio at 50 Hz). It ranks second to MingTok-Audio on Mandarin PESQ (4.21 vs. 4.163) but ahead of it on English PESQ (4.04 vs. 4.125) (§5.1, Table 3).
On the speech-domain understanding side of the X-ARES benchmark (linear probing across eleven speech tasks), DashengTokenizer’s unified feature achieves the best score on four tasks (CREMA-D emotion recognition, LibriCount speaker counting, RAVDESS emotion, vocal sound classification) and ranks second on two others, but shows a marked gap on intent classification (FSC) and ASR (LS100h) relative to purely semantic encoders such as Whisper-Large-V3 and HuBERT (§5.2, Table 5).
The paper’s non-speech results (text-to-audio on AudioCaps, text-to-music on MusicCaps, speech enhancement on Valentini/DNS1, and general-sound/music reconstruction and understanding) are out of this wiki’s scope and are not detailed here.
Novelty Assessment
The genuinely new element, for the speech-relevant scope tracked by this wiki, is architectural: a single-stage acoustic-injection design that keeps a semantic encoder frozen and adds a small trainable acoustic residual regularized by an explicit semantic-preservation loss, rather than the multi-stage acoustic-modeling-then-semantic-distillation pipeline used by the closest prior speech-only system (Ming-UniAudio). This simplification is reflected in the reconstruction results, where DashengTokenizer is competitive with or ahead of that prior system on SEED-TTS PESQ despite requiring only one training stage instead of three.
Within this wiki’s narrow scope, the contribution is best read as an existence proof that a general-purpose (non-speech-specific) tokenizer, when evaluated on speech reconstruction, is competitive with dedicated speech-community codecs; the paper does not claim, and does not attempt, a TTS- or VC-specific contribution.
Field Significance
moderate — Within the reconstruction-fidelity literature the paper contributes an architecturally distinct, single-stage alternative to multi-stage semantic-distillation codec training, and its SEED-TTS benchmark provides a useful comparison point against speech-community codecs (Mimi, XCodec 2.0, SNAC, XY-Tokenizer). Its significance to the TTS/VC/spoken conversational agent field specifically is limited: it is a general-purpose audio tokenizer whose own generative demonstrations are entirely non-speech, so it does not directly advance any TTS or VC method.
Claims
- supports: A continuous tokenizer that injects a lightweight acoustic residual into a frozen, high-dimensional semantic embedding can match or exceed discrete neural speech codecs on speech reconstruction fidelity, even at a lower frame rate.
Evidence: On SEED-TTS ZH/EN, DashengTokenizer (25 Hz) reaches PESQ 4.163/4.125 and STOI 0.988/0.987, exceeding SNAC (1.841/1.804), Mimi (2.05/2.01), XCodec 2.0 (2.19/2.37), and XY-Tokenizer (2.27/2.14), all of which operate at higher or comparable frame rates. (§5.1, Table 3)
- refines: Retaining a semantic encoder’s discriminative quality while adding acoustic detail for reconstruction is not free: unified semantic-acoustic representations remain strong on tasks tolerant of acoustic/paralinguistic variance but can underperform purely semantic encoders on tasks requiring fine linguistic abstraction.
Evidence: DashengTokenizer’s unified feature scores best on CREMA-D, LibriCount, RAVDESS, and vocal-sound classification but shows a substantial gap on intent classification (FSC, 83.39 vs. Whisper-Large-V3’s 97.78) and ASR (LS100h, 68.71 vs. Whisper-Large-V3’s 90.0 and HuBERT’s 82.45), attributed to the model’s retention of acoustic variance interfering with pure semantic abstraction. (§5.2, Table 5)
- supports: A single-stage acoustic-injection training recipe, avoiding the multi-stage acoustic-modeling-then-semantic-distillation pipeline used by prior semantic-acoustic codecs, can reach competitive speech reconstruction quality while substantially reducing training complexity.
Evidence: Only the acoustic encoder, a semantic-preservation loss, and the decoder are trained (the semantic encoder stays frozen and is retained at inference), in contrast to Ming-UniAudio’s three-stage pipeline (acoustic modeling, semantic distillation, fine-tuning); DashengTokenizer still reaches PESQ 4.163/4.125 on SEED-TTS ZH/EN, ahead of Ming-UniAudio’s MingTok-Audio on the English subset (4.04) and close behind it on Mandarin (4.21). (§2, §5.1, Table 3)
- supports: An explicit loss term that regularizes an injected acoustic residual toward its paired semantic embedding is necessary for high-fidelity reconstruction, since semantic features alone are largely reconstruction-incapable.
Evidence: In the feature ablation, the semantic-only feature collapses to PESQ 1.04 on both SEED-ZH and SEED-EN, while the acoustic-only feature reaches PESQ 4.178/4.131 and the unified feature (semantic + regularized acoustic) reaches 4.163/4.125, near-parity with the acoustic-only signal. (§5.5, Table 11)
Limitations and Open Questions
The paper’s own framing and every generative experiment (text-to-audio, text-to-music, speech enhancement) are tri-domain or non-speech; it never performs TTS or VC generation, so its relevance to this wiki is confined to the reconstruction and understanding benchmarks discussed above. Within that narrower scope, the SEED-TTS reconstruction comparison does not control for parameter count or total training data across systems (DashengTokenizer’s semantic encoder alone is 630M parameters, considerably larger than lightweight discrete codecs such as SNAC or Mimi), so part of its reconstruction advantage may reflect model scale rather than the acoustic-injection mechanism specifically. The X-ARES speech-understanding gap on ASR and intent classification (§5.2) is also only partially explained in the paper and is presented as a trade-off rather than resolved.
Wiki Connections
- Neural Audio Codec — proposes a continuous, single-stage semantic-plus-acoustic tokenizer and benchmarks its speech reconstruction fidelity directly against established discrete speech codecs on SEED-TTS.
- Self-Supervised Speech — depends on a frozen, self-supervised-pretrained (masked-audio-modeling) semantic encoder (MiDashengLM/Dasheng lineage) as the core representation onto which acoustic detail is injected.
- Evaluation Metrics — runs a systematic, multi-codec reconstruction and understanding comparison (PESQ, STOI, X-ARES linear probing) that situates a new tokenizer design against established speech-community codecs.
- Seed-TTS — its SEED-TTS speech dataset is the direct evaluation set for DashengTokenizer’s speech reconstruction benchmark (Table 3).
- Moshi — Moshi’s Mimi codec is used as a discrete-codec reconstruction baseline on SEED-TTS, substantially outperformed by DashengTokenizer’s continuous representation.
- XY-Tokenizer — used as a discrete low-bitrate speech codec baseline in the SEED-TTS reconstruction comparison.
- Ming-UniAudio — identified as the most closely related prior work; DashengTokenizer is explicitly contrasted against its speech-only, three-stage (MingTok-Audio) training pipeline.
- Emilia — one of the speech corpora (English and multilingual subsets) used in DashengTokenizer’s training data mixture.
- FlexiCodec — used as a discrete-codec baseline in the X-ARES speech-domain understanding comparison.
- Vocos — DashengTokenizer’s acoustic decoder is a scaled version of the Vocos architecture.